
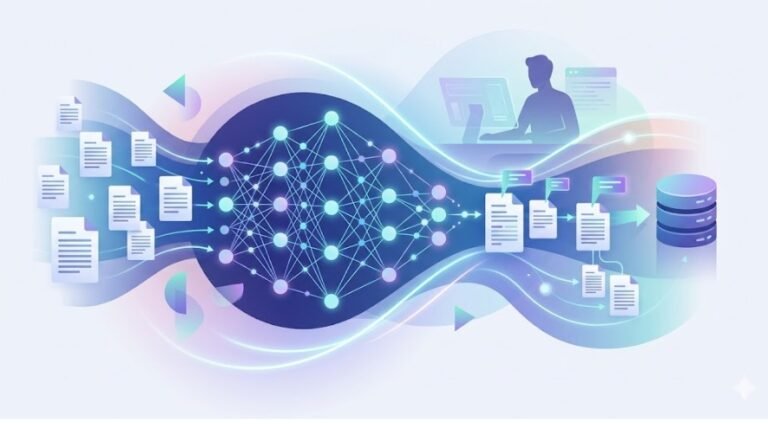
Modern NLP pipelines are rapidly adopting auto-labeling as a foundational layer. It becomes an essential step, especially when the data scales. AI-assisted systems are helping teams with data labeling instead of relying on manual annotation. Furthermore, they also refine it through human-in-the-loop workflows. The results? This hybrid approach leads to:
1) Quality maintenance.
2) Reduced costs
3) Improvement in speed.
Let’s figure out why auto-labeling matters:
Why Auto Labeling Matters
According to studies, 60-80% of project time is spent on data labeling. It also takes up to 50% of the total budget. This urges the need for auto-labeling in today’s AI-driven era. The fact also shows that auto-labeling is the most challenging stage in AI development.
As a matter of fact, manual labeling can be expensive as well as slow. This leads to challenges when the data scales.
Auto Labeling When Data Scales
Auto-labeling makes use of heuristics and models to create labels for data at scale. As a result, we get consistent and faster progress for large datasets without errors. However, it is still recommended to implement human review as AI can not give you 100% correct results.
Let’s explore some popular platforms that allow AI-assisted labeling with their limitations and best-fit points:
Auto Labeling Approach by Different Platforms
Leading platforms follow different approaches when it comes to auto-labeling. For example,
Labelbox has a strong focus on enterprise -grade workflows. Reinforcement learning from human feedback makes it expensive and suitable only for large ML teams.
V7 Labs (Darwin) is primarily a computer vision platform that supports image and video annotation workflows. It also offers some document processing capabilities, but its core strength lies in vision-based data. The best part? They have affordable pricing that makes it an attractive option for new businesses.
Encord follows a multimodal approach. For example, it integrates advanced models like SAM 2 and GPT-4.0. These models help them handle complex data types.
A strong option with human-in-the-loop systems and computer vision is SuperAnnotate. However, this platform is not specifically customized for NLP workflows.
Finally, there is Dataloop that extends its capabilities by offering a full MLOps pipeline. This covers deployment as well as annotation. However, this platform is not suitable for NLP tasks with heavy documents.
Challenges and Limitations of Auto Labeling in NLP Pipelines
Here are some major challenges of auto-labeling in NLP pipelines:
Biases in Model
An existing dataset is used for auto-labeling. If there are any biases, they will be carried forward with new tasks. These existing training data biases will cause changes and unexpected results in sensitive applications. One such example is sentiment analysis.
No Deep Contextual Understanding
Auto-labeling poses some real challenges when dealing with domain-specific labels. It also cannot understand sarcasm or cultural nuances. The output labels might seem correct, apparently. However, they will lack semantic accuracy.
Reliance on Automation
ML teams should not rely too heavily on automation, as there is always a need for human involvement in the loop. The requirement becomes obvious specially when dealing with large datasets. Even minor errors can have large and serious consequences. As a result, performance is impacted.
Continuous Monitoring Is Required
When new data patterns arrive, the auto-labeling model needs to be retrained. It should remain relevant to every new piece of information entering the system. A lack of it can lead to wrong results. Teams monitor new data patterns and regularly update their auto-labeling models.
Key Takeaways
Production teams should adopt a hybrid approach when it comes to AI-assisted labeling.
A hybrid approach gives fast results with accuracy as well as consistency.Auto-labeling NLP pipelines prevents large-scale errors for data.With time, auto-labeling for NLP pipelines has become foundational.
FAQs
How Do ML Teams Deal With Biases Within Automated Data Labeling?
Old data patterns withing auto-labeling model lead to biases when new data is released. To prevent this, ML teams use “Golden Datasets”. These datasets maintain AI performance by serving as benchmarks. It ensures objectivity and fairness within the NLP data pipelines.
What Is Active Learning in Auto-Labeling?
In active learning, the system identifies uncertain data points and sends them forward for human review. It will help the teams focus only on the difficult parts of the data. The results?
Teams get an auto-labeling model that delivers higher efficiency and fast, real-time learning.
Is Auto Data Labeling Suitable for Legal and Healthcare Industries?
Yes, but auto-labeling poses domain-specific challenges in the legal and healthcare industries. In this case, teams adopt silver labeling. Industry-specific rules and custom dictionaries are added as a top layer within the model. This ensures accurate terminology.
What Are the Differences Between Programmatic and Pre-labeling?
Pre-labeling refers to a model that suggests a label, and then teams review it and correct any mistakes.On the other hand, programmatic labeling uses programmatic functions to generate labels based on trained keywords and patterns.
Programmatic labeling is suitable for complex NLP tasks.
How Much Human Review Is Required for Auto-Labeling?
It depends on the risk acceptance percentage for a project. Only 5-10% of data review is required when dealing with basic datasets. However, when dealing with large datasets, such as medical records, the HITL requirement is high. This ensures clinical accuracy, compliance, and a safe system.
Can Auto Labeling Help in New Projects with Zero Labeled Data?
Zero-labeled data is one of the biggest challenges for new projects. In this case, ML teams use few-shot or zero-shot learning that creates an initial dataset. This dataset works as a foundational structure to train the model for new projects.
